Self-Supervised Free Lunch for Flow Map Training
TL;DR: A flow map can supervise its own features. Its composition rule gives two views of an image and a teacher with no extra forward pass, and no external encoder.
Why this matters
Diffusion training seems difficult partly because of the semantic structure that has to come out of it. We have seen representation autoencoders, representation generation and representation alignment. Much of this work says the same thing: diffusion training needs some form of self-supervised signal to train faster and generate better.
Since I was mostly working on few-step models, that is, flow maps, I noticed they are in principle a knowledge distillation algorithm: a student tries to distill from a multi-step teacher. Looked at closely, the student and the teacher see two views of the same data. The teacher gets the cleaner one and the student the noisier one. This gives another dimension of consistency, in feature space, without any additional forward pass. That is the first free lunch for flow map training.
Then I realized that even when you align features across these free views, their quality is still below what self-supervised learning gives. A distributional regularizer like SIGReg can also be applied to diffusion to shape its representations. That is the second free lunch.
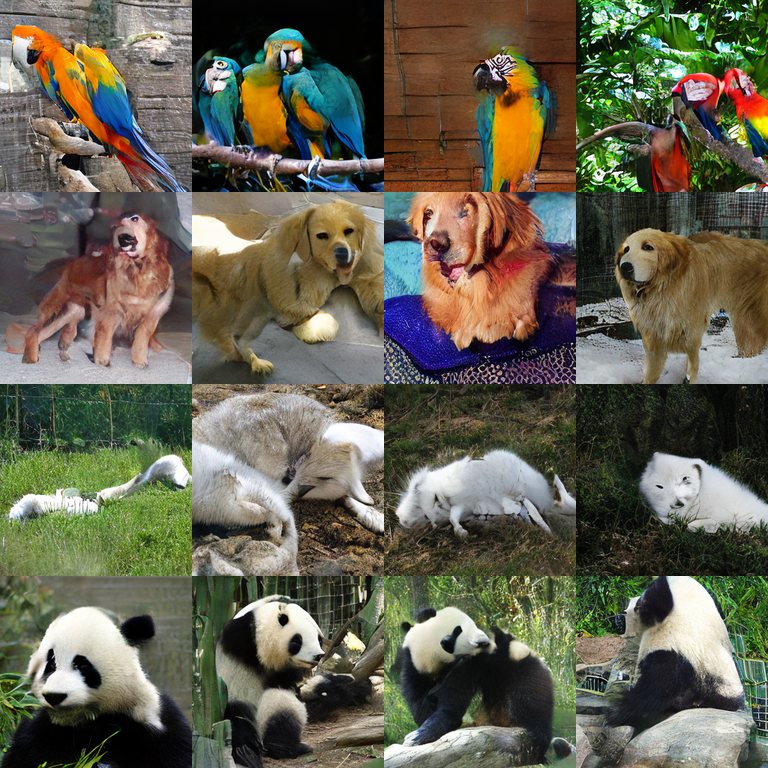
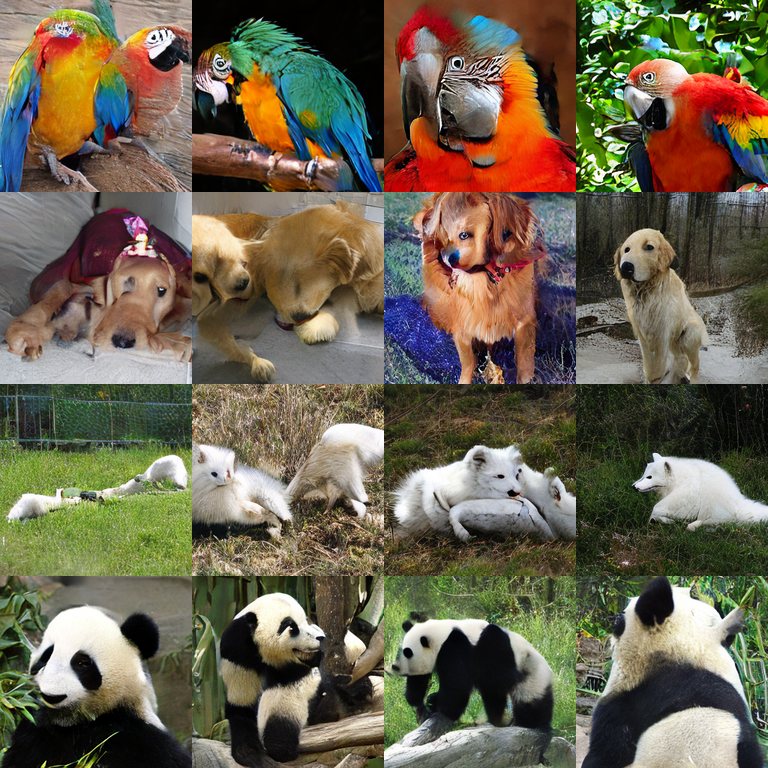
One-step samples, ImageNet 256×256
MeanFlow SiT-B/2, 1 step
Shortcut DiT-B/2, 1 step
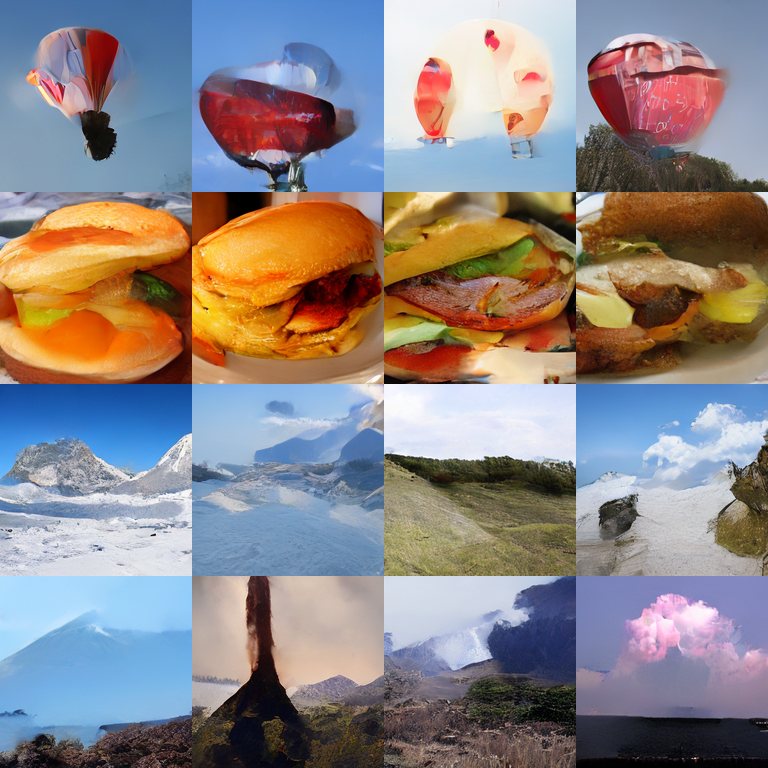
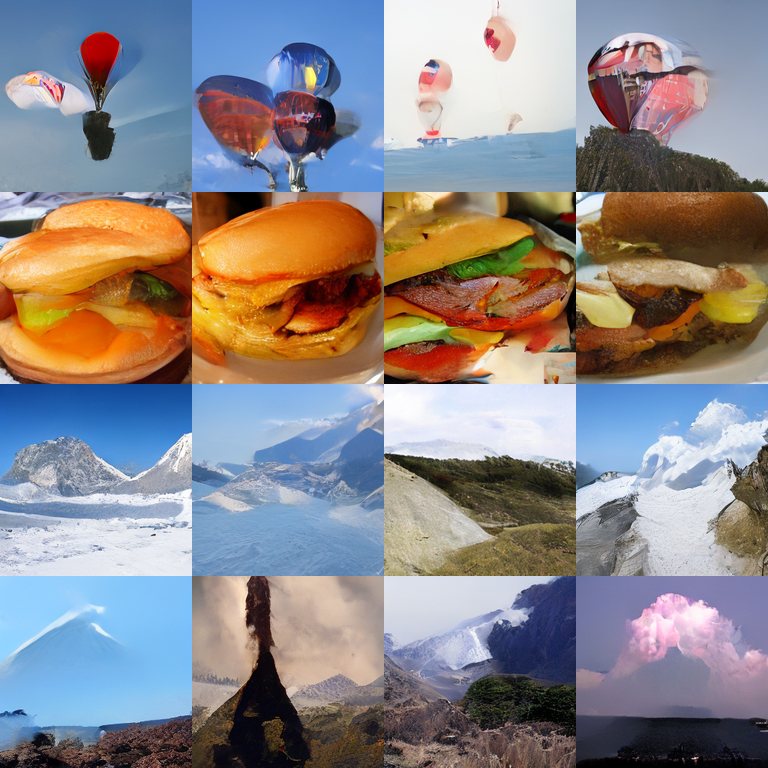
Uncurated. Each row is one class; both grids in a pair use the same classes and noise. Models trained for 1.2M steps. These samples come from an earlier version of FeCo (feature loss only, without SIGReg), not the final method.
Method
- Student. An early block of the online model reads the noisier view.
- Teacher. A deep block of the EMA model reads the cleaner view. No gradient flows into it.
- Predictor h. A small network that maps the student's features to the teacher's. The FeCo loss compares the two.
- SIGReg (from LeJEPA). It acts on the online model's features at the teacher's depth and pushes their distribution toward an isotropic Gaussian.
Both terms are added to the usual flow-map loss.
Why it is free
Every flow-map family builds its training target by moving along the path to a cleaner point. FeCo reads the teacher features at that point, so it needs no extra forward pass.
| Family | Teacher view | Already there because |
|---|---|---|
| Shortcut Models | EMA half step | its target chains two half steps |
| MeanFlow | tangent from its JVP | its target runs a JVP |
| LSD | landing point of its target forward | its target runs that forward |
What remains is the small predictor and the SIGReg statistic.
Preliminary results (ImageNet-100 speedrun)
| Family | Baseline | FeCo | + SIGReg | REPA |
|---|---|---|---|---|
| MeanFlow (SiT-B/2) | 57.3 | 51.8 | 48.9 | 51.2 |
| Shortcut (DiT-B/2) | 139.9 | 135.4 | 116.8 | – |
| LSD (SiT-B/2) | – | 72.7 | 64.6 | – |
Preliminary, ImageNet-100 speedrun: one-step FID, mean of 2 seeds, 39.5k training steps, not the paper budget. REPA aligns with a frozen DINOv2 encoder. No LSD baseline in this study.
Main results
BibTeX
@article{awal2026feco,
  title  = {Self-Supervised Free Lunch for Flow Map Training},
  author = {Awal, Rabiul and others},
  year   = {2026},
  note   = {Preprint coming soon}
}